Direct answer: WebMCP is an emerging way for websites to describe useful actions as structured tools that an AI agent can discover and invoke. It does not replace a good website, search visibility or APIs. It adds an agent-facing interaction layer to the human-facing web.
For thirty years, websites have been designed mainly for two machine audiences. Search crawlers read pages to rank and retrieve them. Browser software renders those pages for people. AI agents introduce a third audience: software that may arrive with a user’s goal, inspect available capabilities and attempt to act.
I call these agents digital citizens as a metaphor, not a legal status. They can search, compare, request, book, buy or prepare work, but they should operate inside authority granted by a human or organisation. That distinction matters. The interesting future is not a web full of uncontrolled bots. It is a web in which delegated software can understand what it is allowed to do, carry out narrow actions reliably and leave evidence behind.
What WebMCP actually is
The WebMCP draft specification describes a browser API through which a web application can expose JavaScript-based tools to AI agents. The proposal is being developed in the W3C Web Machine Learning Community Group, but it is not currently a W3C Standard. That maturity caveat should travel with every serious explanation of the technology.
Google’s official Chrome WebMCP documentation explains two complementary approaches. A site can register tools through JavaScript, and it can annotate HTML forms so an agent has a more explicit description of what a page feature does and which inputs it expects. The aim is to replace fragile guesswork—finding a button by its colour or position—with a structured contract.
The practical difference is substantial. A visually capable agent can already attempt to use ordinary websites by reading the page and simulating clicks. That works until a label changes, a modal appears, a field is ambiguous or an irreversible action sits beside a harmless one. WebMCP gives the site a vocabulary for saying: this tool searches stock; this one prepares a quote; this field is a postcode; this action needs confirmation.
WebMCP is related to MCP, but it is not the same thing
The broader Model Context Protocol architecture standardises how an AI host connects to MCP servers that expose tools, resources and prompts. It separates the host, client and server, uses capability negotiation, and is designed so focused services can be composed without every integration being invented from scratch.
WebMCP brings a related tool idea into the browser tab. The website itself describes capabilities that are meaningful in the current page, origin and authenticated session. That matters because the browser already understands cookies, permissions, user presence, same-origin boundaries and the visible state of the application.
| Layer | Primary job | Typical boundary |
|---|---|---|
| Search and structured content | Help systems discover and understand information | Public pages and indexes |
| MCP server | Expose tools, resources and prompts to an AI application | Local or remote service connection |
| WebMCP | Expose structured tools from a live web application | Browser tab, site origin and user session |
| Human interface | Let a person inspect, decide and act | Screen, browser and account |
Developers wanting to see implementation patterns can also use Google Chrome Labs’ open-source WebMCP inspection and evaluation tools. For a practical tutorial outside the specification itself, DataCamp’s agent-ready website walkthrough is one of the prominent current search results. Both are more useful references than vague claims that adding a script suddenly makes a website “AI optimised”.
Why agent-ready websites may gain an advantage
The first advantage is reliability. If an agent can call a named product-search tool with a defined schema, it has less reason to interpret the visual page, guess which filters matter or scrape a changing layout. The second is control. The website can decide what to expose, validate inputs, distinguish read-only queries from consequential actions and require human confirmation where appropriate.
The third advantage is commercial. An agent choosing between two suppliers may favour the one whose availability, specifications, eligibility rules and quotation steps are clear enough to use. This is not because WebMCP creates a Google ranking factor; there is no evidence of that. It is because machine-actionable businesses can be easier for delegated software to transact with after discovery.
This is where implementation companies are beginning to create a market around “agent-ready” sites. One example is TEMRIK, which presents regional business-system offerings through its global website, Australian website and United Kingdom website. The relevant idea is not that one vendor owns the category. It is that early practitioners are translating an emerging browser standard into the less glamorous work of schemas, permissions, workflows, validation and safe handoffs.
The “digital citizen” changes website strategy
Most website strategy assumes a funnel: a person searches, visits a page, reads a proposition and converts. An agent may compress that journey. It could receive a goal such as “find three compliant suppliers, compare lead times and prepare the best option for approval”. It may visit many sites, reject those that cannot provide reliable data, and return only the shortlist.
That creates a new kind of competition. A business will still need credible content and recognisable trust signals for people. It may also need structured capabilities for machines: search inventory, check service coverage, validate eligibility, prepare a quote, reserve a slot, retrieve evidence or initiate a support case. The website becomes both publication and operating surface.
There is a strategic warning here. Exposing more tools is not automatically better. An agent-facing interface should be designed around real user goals, not a catalogue of every internal function. Tool descriptions must be clear, outputs predictable and high-consequence actions gated. The strongest implementations will make the safe path the easy path.
Could agents pay for data?
Yes—and this is already moving from theory into protocol design. Stripe and Tempo’s Machine Payments Protocol lets an HTTP-addressable service, API or MCP endpoint respond with a payment request. Stripe describes usage-based patterns in which software can pay per request or session rather than relying on a human to open an account and configure billing in advance.
Coinbase’s x402 protocol revives HTTP’s “402 Payment Required” status for internet-native payments. Its examples include agents paying for APIs, software and context. Coinbase has also documented an x402-enabled premium search flow in which an agent can encounter a price, pay for fresh information and continue its task in the same interaction.
Google’s Agent Payments Protocol guidance addresses a different but complementary problem: how to prove who authorised a purchase and which limits apply. Typed mandates can bind an agent’s action to allowed merchants, spending limits and a particular cart, preserving a route back to human intent.
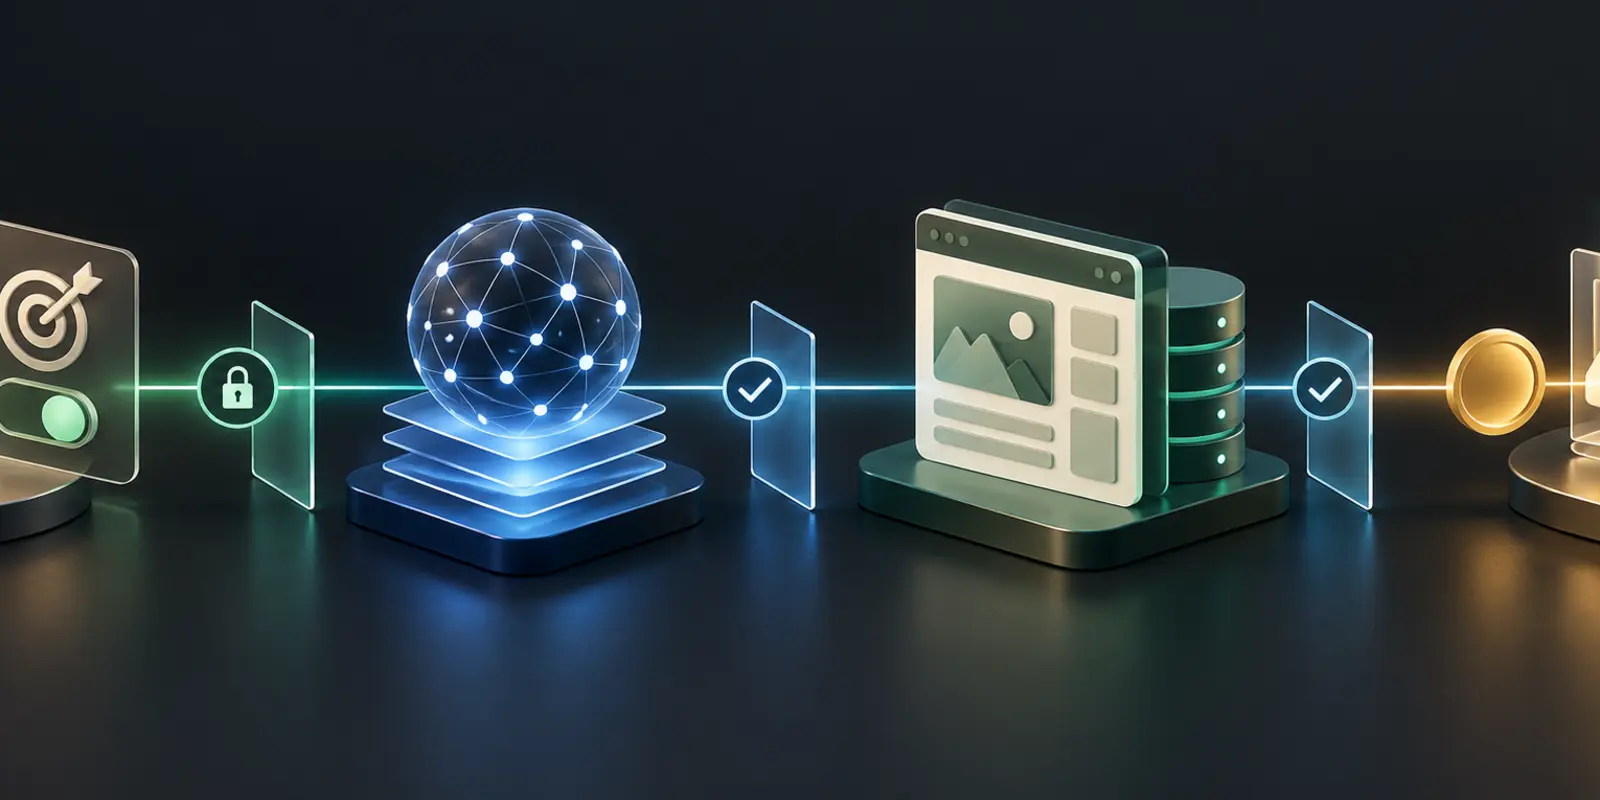
A user delegates a task → an agent discovers a useful capability → the provider prices premium data or computation → the agent pays within its authority → the result and payment evidence return to the user.
This could create markets that conventional subscriptions serve badly: a few cents for a current planning record, a one-off engineering dataset, a specialist model inference, a verified product certificate or an enriched search result. The promise is granular access. The risk is equally clear: unclear authority, low-quality data, silent overspending, fraud and no dependable relationship between payment and fulfilment.
Recent academic work on agent-payment protocols reinforces that caution. A 2026 formal analysis of x402, MPP, ACP and AP2 argues that delegated authorisation must remain consistent with the economic and service effects that follow. In plain English: it is not enough to prove that a payment message was signed. The system must preserve what the user intended, what was bought, from whom, for how much and whether the promised result was delivered.
What a responsible WebMCP programme should include
1. Start with genuine user goals
Choose a small number of tasks people already try to complete. Search, availability, quotation and support intake are better starting points than exposing an entire back office.
2. Separate information from consequence
Reading a catalogue is not the same as placing an order. Preparing a quote is not the same as accepting it. Tool design should mark that boundary explicitly.
3. Keep human authority visible
Identity, scope, approval and revocation should be designed before autonomy. A user should be able to see what an agent is about to do and understand the resulting commitment.
4. Test agents, not just forms
A valid schema can still describe a confusing tool. Test whether different agents select the right capability, provide valid arguments, recover from errors and stop at approval gates.
5. Preserve the ordinary web
Accessible HTML, fast pages, clear copy, structured data and crawlable evidence remain essential. WebMCP should improve the site for an additional user class, not hide a weak human experience.
The real opportunity
The important shift is not “bots are coming”. Bots have been on the web for decades. The shift is that agents can increasingly arrive with intent, context and limited authority. A crawler wants a document. A digital citizen wants an outcome.
WebMCP offers a plausible interface for that world because it lets websites describe action in a language agents can inspect while retaining the browser’s familiar security boundaries. It is early, experimental and certain to evolve. But the direction is credible: websites will need to communicate not only what they say, but what they can safely do.
The businesses that benefit will not be those that add the most AI language to their homepages. They will be the ones that make their information trustworthy, their actions explicit, their permissions narrow and their evidence durable. That is how the web becomes useful to its next class of visitor without becoming less accountable to the people it serves.
Research and further reading
Editorial disclosure: independent commentary for general information. External links are provided because they add source or implementation context. No commercial relationship or endorsement is stated or implied.